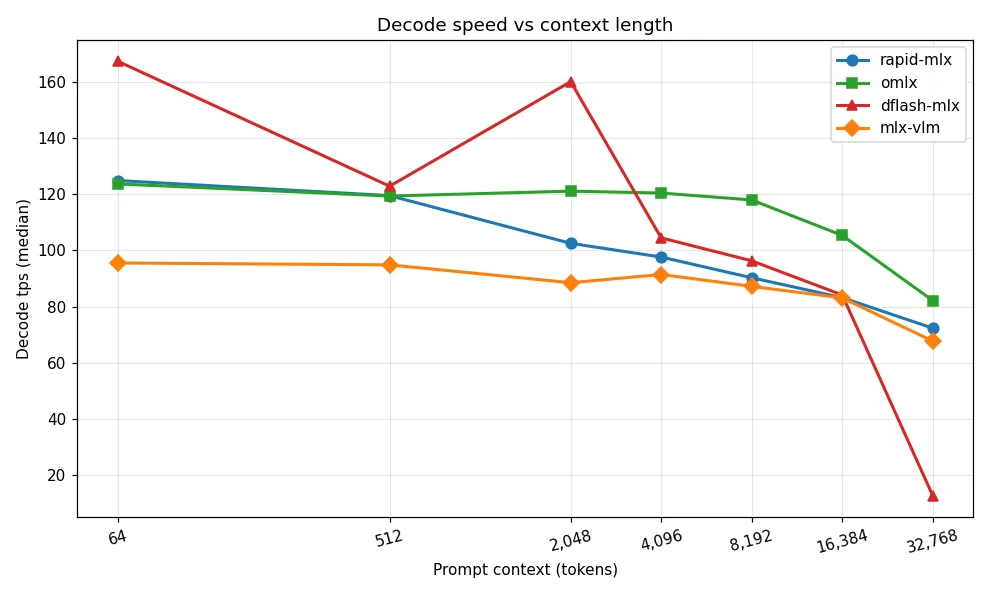
rapid-mlx vs oMLX: MLX Inference Benchmark on Apple M5 Max (35B LLM)
Head-to-head MLX inference benchmark on Apple M5 Max (64 GB unified memory): rapid-mlx vs omlx vs dflash-mlx vs mlx-vlm running a 35B LLM — tokens/sec, time-to-first-token, memory use, and which framework to pick in 2026.
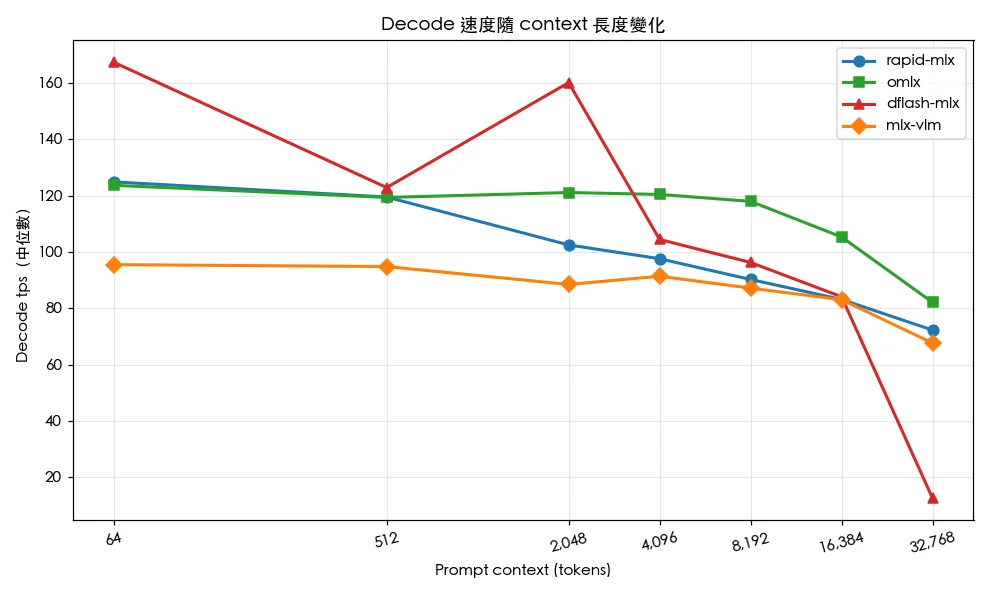
MLX 推論框架基準測試:Apple Silicon M5 Max 跑 35B LLM 實測比較
在 Apple M5 Max(64 GB 統一記憶體)上以 35B 量化 MoE 模型實測 rapid-mlx、omlx、dflash-mlx、mlx-vlm 四大 MLX 推論框架,涵蓋 64 至 32K Tokens 七個上下文長度的解碼速度、TTFT 與穩定度比較,並提供企業地端 AI 選型建議。原始基準測試資料由 ywchiu/mlx_benchmark_lab 開源公開。
開源 AI 模型比較 2026:DeepSeek V4.1、Qwen 3.8、GLM 5.3、Mistral Large 4 選型指南
比較 DeepSeek V4.1-Flash-1017、Qwen 3.8、GLM 5.3、Kimi K3、Mistral Large 4、Muse Spark Open、Nemotron 3.5、Gemma 4 與 TAIDE,從授權、部署、成本與資安,梳理台灣企業的選型考量。