How does AI detect fake news? Five methods and what they cannot do
AI detects fake news not by reading an article and declaring it true or false, but by finding anomalous signals in content, sources, diffusion, accounts and imagery, narrowing the scope for human verification. This article sets out the principles and limits of five methods, and how to connect them into a verification workflow.
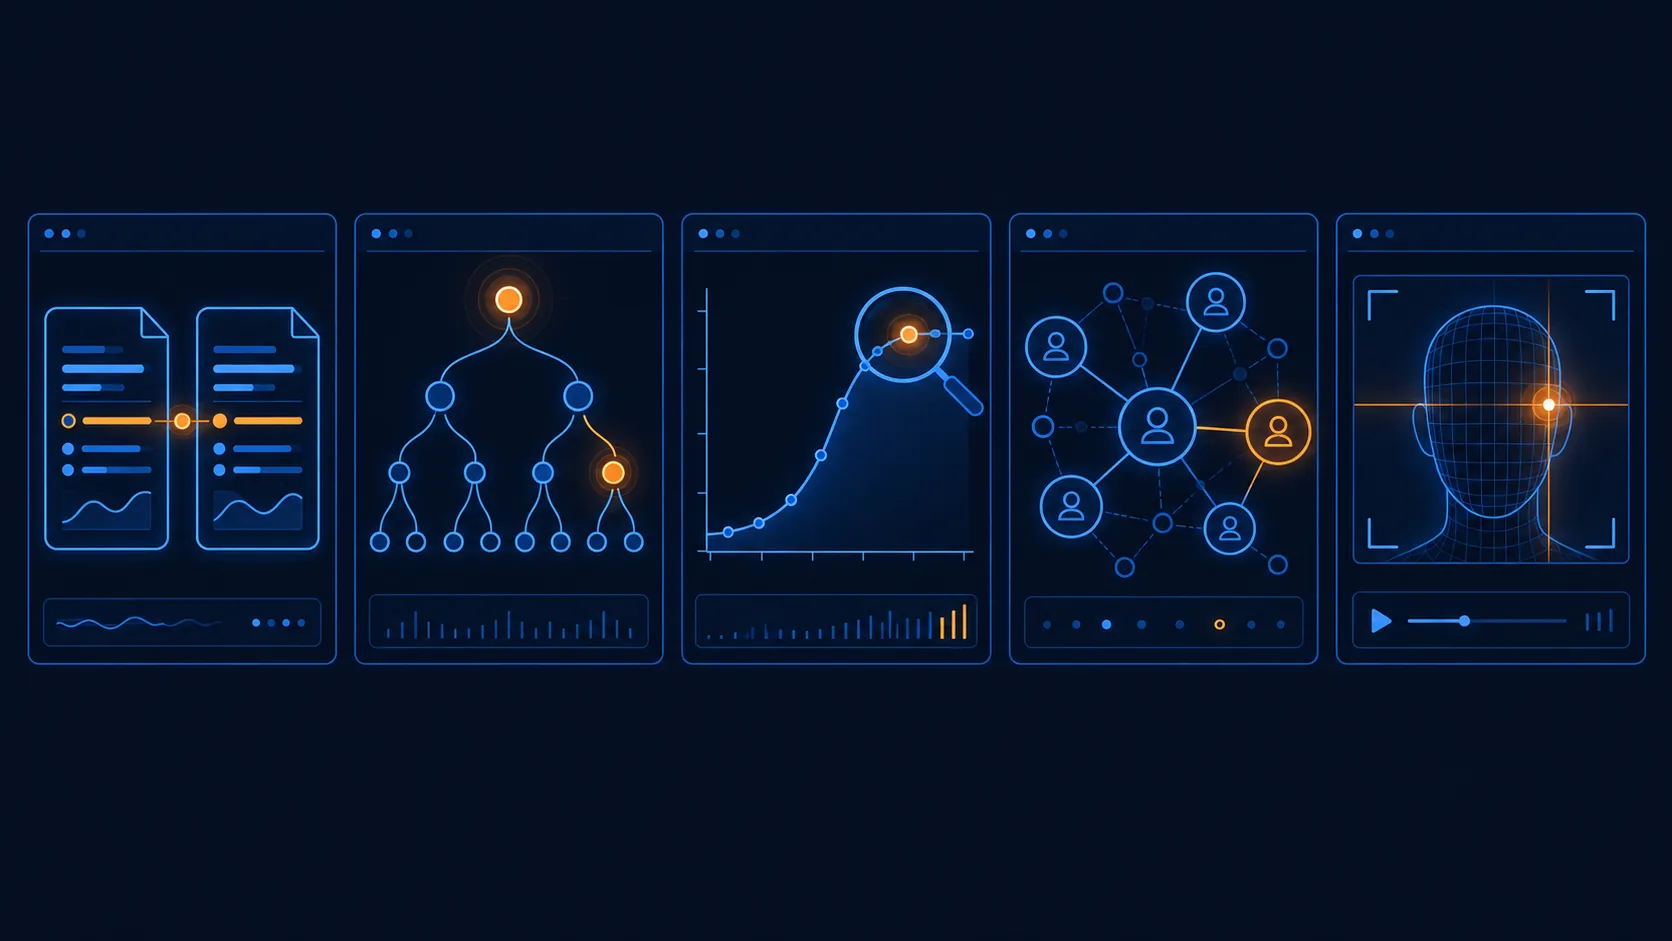
Quick answer: how does AI detect fake news?
AI can detect fake news from the five types of signals covered in this article: claim matching, source credibility and origin tracing, diffusion patterns, coordinated account behavior, and multimodal analysis of images and video. It helps narrow the scope of verification and spot anomalies earlier, but it cannot determine truth or falsehood on its own; what the system produces is suspicious signals and investigative leads, and the determination of truth, attribution and any response remain decisions for human verification.
First, be clear: 'detection' and 'fact-checking' are two different things
Before evaluating tools, distinguish detection from fact-checking. Detection answers 'which content deserves a look first'; it is filtering and ranking, and can be automated at scale. Fact-checking answers 'is this claim true'; it requires finding primary sources, comparing against official records and standing behind the conclusion.
Treating a screening label as a fact-checking conclusion can overlook the evidence and the model's limits; the system should explain why it flagged an item, and then a fact-checker makes the judgment. One more distinction is needed: truth or falsehood is judged by fact-checkers on the evidence, while whether something is illegal is determined by the competent authority according to law; being found false does not mean being illegal.
The term 'fake news' has its own limits. In the 2017 report Information Disorder, written by Wardle and Derakhshan for the Council of Europe, information disorder is divided into misinformation, disinformation and malinformation, and the authors argue that the term 'fake news' is inadequate to describe these phenomena. Content worth attention is also not necessarily fabricated; for example, a genuine photo paired with the wrong time and place.
Five detection methods: principles, scope and limits
The five methods look at different layers of signal and can be combined in practice. Each is described below in the same format: principle, what it is good at catching, possible misjudgments, and the data it needs.
1. Claim matching
Principle:Break the content to be checked into verifiable claims, such as a figure, a policy or a quotation, then compare them by semantic similarity against a database of claims that have already been fact-checked. The focus is meaning rather than wording, because the same claim may be reworded, retitled, translated or turned into an image card and circulated again.
Good at catching:Old claims that circulate again and their variants, such as existing rumors that resurface during typhoons, epidemics or elections, and previously checked content in new packaging. Public results from fact-checking organizations such as Taiwan FactCheck Center and MyGoPen, and Cofacts, a crowdsourced fact-checking platform, can serve as references for matching; confirm licensing and content quality before using them.
Possible misjudgments:Reports that quote a rumor in order to clarify it may be mislabeled because of high similarity; if a claim changes a place or a figure, similarity may fall below the threshold. The fundamental limit is that when there is no corresponding fact-check record, an existing fact-check conclusion cannot be provided directly.
Data needed:A continuously updated database of checked claims, a semantic model that can handle colloquial Traditional Chinese rewrites, and the full content including text on image cards.
2. Source credibility and origin tracing
Principle:On one side, assess the publisher's record, such as when the site was created, whether it has repeatedly published false content, and whether the author and contact information can be checked; on the other, trace back through reposts and citations to find when and where the claim first appeared in the data that can currently be observed, and what rewrites it went through along the way.
Good at catching:Content farms disguised as news sites, messages that use the name of a legitimate institution without authorization, and screenshots of unknown origin that are forwarded widely.
Possible misjudgments:Relying too heavily on historical records may underrate a newly founded legitimate outlet, and may let through an occasional error from a source with a good reputation. Origin tracing is limited by data coverage: closed groups that cannot be seen and deleted posts can cause the earliest observable version to be mistaken for the origin.
Data needed:Cross-platform historical data with timestamps, records of source attributes, and repost and citation relationships; the quality of tracing depends on whether data coverage, timestamps and relationship records are complete.
3. Diffusion patterns
Principle:Observe the shape of how a message spreads across time and platforms. Phenomena such as a sharp rise in volume within a short time, the same narrative appearing on several platforms almost simultaneously, and dense activity at off-peak hours are listed as signals to check, then compared against natural events, scheduled publishing and the baseline for the topic.
Good at catching:Abnormal volume, cross-platform relay (for example, appearing first on a forum and then spreading on short video and messaging groups), and topics whose volume growth clearly does not match the topic baseline.
Possible misjudgments:Breaking events, reposts by well-known figures and media coverage can also cause volume to spike. Abnormal volume only means something is worth a look, not that someone is manipulating; it has to be read against news from the same period.
Data needed:Multi-platform time series, topic and narrative clustering, and enough historical data to establish a baseline.
4. Coordinated account behavior
Principle:Look at the relationships within a group of accounts: whether posting is highly synchronized, whether content is heavily duplicated or only lightly reworded, whether they frequently repost one another, and whether account creation and activity history are unusually concentrated. In its 2020 CIB report, Meta defined coordinated inauthentic behavior as coordinated manipulation of public debate for a strategic goal, with fake accounts at the core of the operation; enforcement is based on the deceptive nature of the behavior, not the content itself. This is also the starting point for this type of method.
Good at catching:Coordinated narrative pushing, creating false consensus with multiple accounts, and the same batch of accounts mobilizing in turn across topics. Because it does not depend on whether the content is true, it can also find manipulation that selectively amplifies genuine information.
Possible misjudgments:Genuine community mobilization, fan support and legitimate advocacy can all be highly synchronized, and organizations that use scheduling tools show similar traits. Coordination signals are a probabilistic assessment: thresholds need tuning to the scenario, account samples need human review, and they do not amount to a finding of illegality.
Data needed:Public account fields and activity records, interaction relationship data and a sufficiently long behavioral history; each platform exposes different fields, so the depth of analysis differs too.
For where coordinated behavior detection fits in the full monitoring workflow, see the description of Fake News Detection and Cognitive Warfare Monitoring System.
5. Multimodal analysis: images, video and deepfakes
Principle:Disinformation can also appear as image cards, screenshots or short videos. Multimodal analysis uses optical character recognition (OCR) to extract text from images so image cards enter claim matching; uses image recognition to check for old images reused in new contexts and for collage edits; and video and deepfake detection checks for inconsistencies in faces, voices and imagery.
Good at catching:Forged official documents or news screenshots, old photos taken out of their original context, synthetic audio and video that borrow a public figure's likeness or voice, and image-only content that text search cannot find.
Possible misjudgments:Compression, transcoding and filters can change the features a model relies on; satire and derivative works are synthetic content but do not necessarily carry deceptive intent. Detection models may degrade when they meet generation methods or data distributions not seen in training, so they should be paired with circulation history and confirmation from the person concerned.
Data needed:The highest-quality version available, circulation history, and continuously updated synthetic samples.
Comparison of the five methods
| Method | Signals examined | Strengths | Limitations | Key data |
|---|---|---|---|---|
| Claim matching | Verifiable claims in the content | Quickly recognizes old rumors and their variants | Cannot provide a conclusion without a fact-check record | Database of checked claims |
| Source and origin tracing | Publisher record and repost paths | Flags impersonated sources and content farms | Cannot see closed groups and deleted posts | Cross-platform historical data |
| Diffusion patterns | Volume curves and cross-platform timing | Flag abnormal spread early | Must be distinguished from genuinely trending events | Time series and historical baselines |
| Coordinated account behavior | Posting rhythm, similarity and interaction networks | Does not depend on whether the content is true or false | May be confused with genuine community mobilization | Public account fields and interaction data |
| Multimodal analysis | Text in images, visual and audio features | Covers content that text retrieval cannot see | Affected by compression and by generation methods the model has not seen | Highest-quality file and circulation history |
Each single method has blind spots. Coordinated-behavior and multimodal analysis can cover what content matching cannot see, but they also need tuning and human verification. The operational recommendation in this article is to combine different signals when ordering reviews, with priority set by signal quality, whether signals are independent of one another, and the likely impact of the event, rather than simply counting how many criteria are met.
What generative AI changes: from literal matching to narratives and behavior
Generative AI makes it easy to produce texts that are similar but not identical. Matching that relies on literal repetition used to catch coordinated copy-and-paste spreading; when every account can obtain a rewrite with a different tone and wording, that kind of matching may lose its effect.
The response is to widen what is observed, not to abandon content analysis: extend matching to the narrative level to see whether different wordings push toward the same conclusion, and at the same time examine time-series data such as account activity history, posting synchrony, interaction networks and the order of appearance across platforms. These signals can also be arranged deliberately, so their effectiveness must still be validated on your own data.
Another misconception is to treat 'was this text written by AI?' as the detection target. Legitimate users also write with generative tools, and once generated text has been rewritten again, the ability of AI-text detectors to identify it may also decline. For disinformation verification, the better questions are whether the claim is credible, and who is pushing it and how.
As the barrier to synthetic audio and video falls, multimodal checks can be built into routine workflows. Preserve the highest-quality version available, along with its URL and capture time, as early as possible, and note whether it is the original file.
Why accuracy figures are not always comparable
Even if every claimed accuracy figure was genuinely measured, the figures may not be directly comparable because evaluation conditions differ. The table below lists four evaluation conditions to check, and questions you can put directly to a vendor.
| Evaluation condition | Why it affects the number | Question to ask |
|---|---|---|
| Dataset | Platform, period, language and topic affect how hard the task is; a score on English news headlines does not predict performance on Traditional Chinese forum posts or image cards. | Which platforms and languages does the test data come from? Does it include topics your agency cares about? |
| Labeling criteria | Whether partial errors, exaggeration, satire and quotes taken out of context count as fake news may be defined differently across datasets; disagreement between annotators also affects how reliable the ground truth is and how the evaluation should be read. | What are the labeling criteria? Who did the labeling? How are disagreements among multiple annotators handled? |
| Positive-to-negative ratio | If the actual share of suspicious content is low, the proportion of false alarms among alerts can still be high even when the model performs well on a test set split evenly between positives and negatives; so look at precision and recall, not just accuracy. | What is the positive-to-negative ratio in the test set? Can you provide precision and recall at a ratio close to the real one? |
| Temporal drift | Topics, wording and tactics change; a test drawn from the same period as the training data may not reflect performance in future periods, so a separate cross-period evaluation should be run. | Is the test data later than the training data? How often is the model updated, and how is performance degradation monitored? |
This article recommends supplementing public benchmarks with backtests on your own scenarios: cover a range of known events and normal periods, and see whether the system can warn before an event expands, and how many false alarms it produces in normal periods.
Building a verification workflow: from alert to external communication
This article recommends connecting detection results to the verification process. The four steps below are the basic setup recommended here; if reviewers and response deadlines are not specified, alerts may not be handled in time.
| Step | What it does | Key design points |
|---|---|---|
| Tiered alerts | Tier by verifiable claims, whether multiple signals hold at the same time, speed of spread and the concrete scope of impact | Write the tiering criteria down in a document so they can be explained and adjusted; do not use political stance as a risk criterion; high-tier alerts have a clear response deadline |
| Human review | Analysts review the reasons and samples the system provides and decide whether to move to formal verification | Record the AI assessment and the human judgment in separate columns so that a system label does not turn directly into a conclusion |
| Keep verification records | Keep screenshots, original links, capture times and related account information | Content may be deleted or edited, so keep the necessary records early; where legal proceedings are involved, confirm the preservation and forensic method separately |
| External communication | Decide from the verification result whether to issue a clarification, who speaks, and through which channels to publish | When clarifying, avoid amplifying the original rumor again; where necessary, work with fact-checking organizations and platform reporting channels |
External communication depends on timing: responding too early may draw attention to a rumor that was still small, while responding too late may let the false account take over the discussion first; diffusion analysis can inform the timing decision.
Public-sector adopters should set the boundaries clearly first. Public sources can still contain personal data, so the scope, purpose, permissions and retention period of collection and storage should be confirmed against the applicable rules and the agency's duties; the goal of monitoring is verification and clarification, not targeting particular speakers, and neither system labels nor coordination signals amount to a finding of illegality.
Further Reading
- Fake News Detection and Cognitive Warfare Monitoring System
- What is cognitive warfare? How it differs from fake news, information manipulation and FIMI
- How to monitor election disinformation: a task checklist for the 60 days before the election
- Defense & Critical Infrastructure Intelligence Solutions
- What is Threat Intelligence? A Complete Enterprise Guide to Threat Intel
- Social listening crisis handling SOP: a 7-step guide to PR crises
FAQ
Want to evaluate how to adopt fake news detection and verification workflows?
LargitData can help take stock of your monitoring scope and existing verification workflow, and explain feasible ways to adopt.
Contact Us